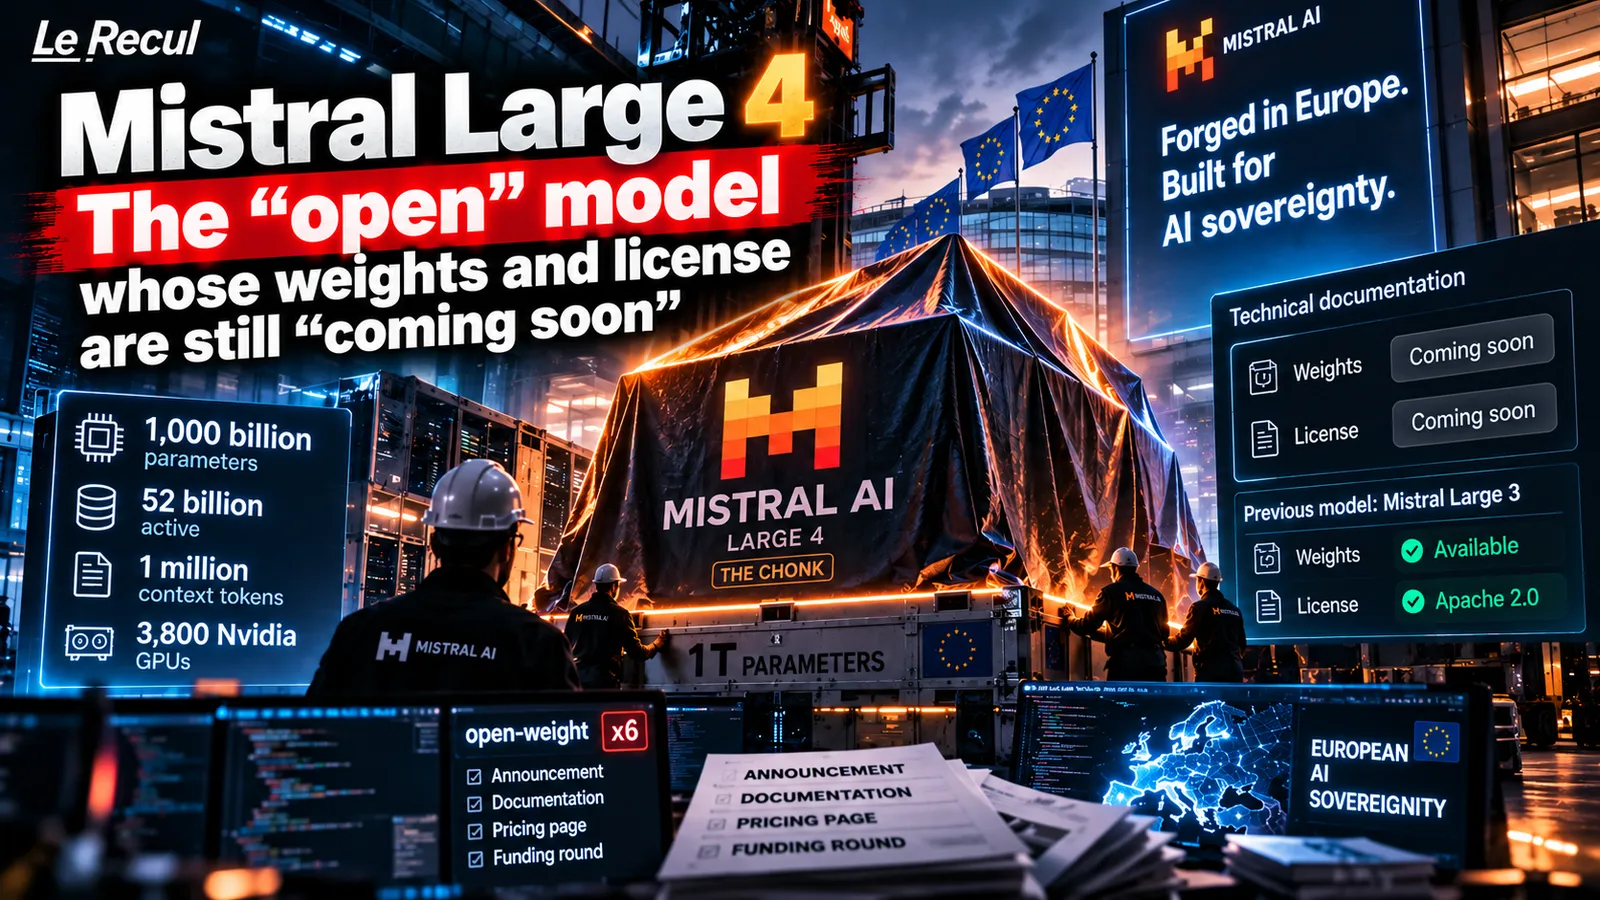
On 6 October 2026, Mistral opened the public preview of its largest model. It is called Mistral Large 4, the company nicknames it “le Chonk”, and the announcement is headlined “Forged in Europe. Built for AI sovereignty”.
The model is a serious piece of work and the numbers are real. But three claims travelled around the coverage without being checked: that it is open, that it is sovereign end to end, and that it holds a world record in cybersecurity. We read the announcement, the technical documentation, the pricing page and the cap table. All three are partly accurate. None of them means what it is being made to mean.
What Mistral announced on 6 October 2026
The specifications, as the company publishes them. One detail is worth noting straight away: the announcement and the documentation do not give quite the same figure.
| Specification | Mistral Large 4 | Mistral Large 3 |
|---|---|---|
| Date | 6 October 2026 (public preview) | 2 December 2025 |
| Total parameters | 1 trillion (announcement) / 1.05T (documentation) | 675 billion |
| Active parameters | 52 billion | about 41 billion |
| Context | 1 million tokens | 256,000 tokens |
| Inputs | Text and image, text output | Text and image |
| Training | 3,800 Nvidia Grace Blackwell GPUs | about 3,000 Nvidia H200 GPUs |
| Licence | "Coming soon" | Apache 2.0 |
| Downloadable weights | "Coming soon" | Yes |
A point of vocabulary that matters for what follows. An “open-weight” model is a model whose parameter files can be downloaded and run on your own machines. That is not the same thing as an “open source” model in the software sense, and above all it is not a guarantee of free use: everything depends on the licence attached to the files.
The word that appears six times, and the two boxes left empty
In the announcement of 6 October, the term “open-weight” or “open weights” appears six times. The model is described as pushing “the frontier of open-weight performance”.
The official model card, on docs.mistral.ai, has a “Weights” tab. It contains a seven-column table. The first two are the ones that count.
| Weights | License | Parameters (T) | Active (B) | Context |
|---|---|---|---|---|
| Coming soon | Coming soon | 1.05 | 52 | 1M |
The weights: coming soon. The licence: coming soon.
This is not a lie, and that needs saying as plainly as the rest: the announcement states in black and white “We will release the weights by the end of the month”. Mistral did not hide the timetable, it wrote it down.
But between “this model is open” and “this model will be open on terms that are not yet known”, there is a gap that most of the coverage erased. As of 9 October 2026, nobody outside Mistral can say on what terms this model may be installed anywhere.
In Mistral’s own catalogue, Large 4 is the only one with no named licence
This is the simplest check, and the most telling. Mistral’s official model catalogue displays a licence badge under each model. Here is what it shows on 9 October 2026.
| Model | Badge displayed | Commercial use |
|---|---|---|
| Mistral Large 3 | APACHE 2.0 | Permitted without conditions |
| Mistral Small 4 | APACHE 2.0 | Permitted without conditions |
| Ministral 3 (3B, 8B, 14B) | APACHE 2.0 | Permitted without conditions |
| Mistral Medium 3.5 | MODIFIED MIT | Conditional |
| Voxtral TTS | CC BY-NC 4.0 | Forbidden |
| Mistral Large 4 | OPEN | Unknown |
Every other open model in the catalogue carries a named licence. Large 4 carries the word “OPEN”, which is not a licence.
The gap between the rows of that table is not theoretical. Apache 2.0 permits commercial use, modification and redistribution with nothing asked in return. CC BY-NC 4.0, which Mistral applies to its own text-to-speech model, forbids commercial use outright. Both are, in everyday language, “open” models.
What Mistral writes on its own pricing page
The question of self-hosting appears in the FAQ on Mistral’s pricing page. The company’s answer, quoted in full:
“Yes, you can self-host our models anywhere. Open-weight models (e.g., Mistral 7B) are Apache 2.0 licensed for research/individual use; while commercial deployments require a Mistral license with separate terms for derivatives and production use.”
That is: yes, you can self-host our models anywhere; open-weight models are Apache 2.0 licensed for research and individual use, while commercial deployments require a Mistral licence with separate terms for derivatives and production use.
That sentence calls for two remarks, and both need making.
The first is that Mistral’s wording is legally questionable: the Apache 2.0 licence is not a licence “for research and individual use”. It explicitly permits commercial use, with no permission required. On this point, Mistral’s page describes its own licence badly.
The second matters more to a reader with a decision to make: whatever the legal reading, it is the company itself that writes, on its commercial page, that a commercial deployment goes through a separate Mistral licence. For an IT department considering installing Large 4 on its own servers, that is the sentence legal counsel will read, not an exegesis of Apache 2.0.
Why the 82 percent record does not say what it seems to
Mistral claims a remarkable cybersecurity result: 82 percent on a test within the Artificial Analysis Cyber Index that asks a model to reproduce a real vulnerability in open source software and then patch it. Mistral adds: “the highest of any model”.
The figure is accurate. But the explanation is in the announcement itself, two paragraphs further down, and it is decisive:
“Several leading closed models, including Claude Opus 5.5 and GPT-6 Astra, score near zero on the same test because they refuse to perform the task.”
Several leading closed models score near zero because they refuse to perform the task.
So the record does not pit one capability against another. It pits a model that agrees to reproduce a vulnerability against models that decline to. It is a gap in moderation policy as much as a gap in capability.
It must be added immediately that Mistral’s argument here is sound, and deserves a hearing: the company explains that defending software often starts with proving a flaw is real, and that the filters in closed models block that legitimate work. It adds that attackers, for their part, jailbreak those same filters. That is a genuine, documented security problem, and Mistral’s choice is defensible.
But “our model is the best in the world on this test” and “our model is the only one that agrees to take this test” are not the same sentence. Only the second is complete.
On the overall index, as it happens, Mistral’s wording is careful and honest: the model ranks “among the top five models globally” and leads “open-weight models developed outside China by a wide margin”. Developed outside China. The company therefore concedes itself that the Chinese open models are ahead.
The sentence about state authorities
This is the least-reported element of the whole announcement, and probably the most important. It sits in the paragraph that sets out the timetable for the weights:
“Until then, we are red-teaming the model in real-world settings with cybersecurity leaders, vetted partners, and state authorities, who will access the same model with reduced moderation and expanded cyber capabilities.”
Until then, we are red-teaming the model in real-world settings with cybersecurity leaders, vetted partners, and state authorities, who will access the same model with reduced moderation and expanded cyber capabilities.
Let us state precisely what this establishes, and what it does not.
Established: state authorities have, ahead of everyone else, a version of the model whose guardrails are lowered and whose offensive capabilities are broadened. Mistral writes this in its public announcement.
Not established: which states, on what criteria they are selected, under what oversight, for how long, and whether that access ends when the weights are published. The announcement says none of this, and we found no clarification elsewhere.
There is nothing illegal here, and nothing surprising to anyone who knows the cybersecurity sector: national agencies have worked with offensive tooling for a long time. What is notable is the conjunction. The same text promises an open release for everyone and describes privileged, capability-extended access for unnamed states. Both promises sit in the same paragraph.
”Forged in Europe”: where the chips come from
The announcement is categorical: “ML4 was trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral’s own datacenters in Europe.”
The machines are in Europe. The chips are designed by Nvidia, an American company, and fabricated in Taiwan. There is no European alternative at that step today, and this is not a reproach aimed at Mistral: it is the state of the industry. But it does draw a precise boundary around what “sovereign” can mean here.
The sovereignty being claimed is operational sovereignty: data is processed on machines owned by Mistral, on European soil, under European law. The announcement in fact puts it accurately — “a European deployment that Mistral operates end-to-end, independently of other digital service providers and under European law”.
It is not supply-chain sovereignty. The model running today genuinely cannot be switched off remotely. The next one will depend on the availability of the next chips, and therefore on decisions taken in Santa Clara and in Washington.
Who owns the European champion
Since the word “sovereignty” sits at the centre of the announcement, the cap table is worth a look. On 8 September 2026, Mistral announced a Series D of 3 billion euros, valuing the company at more than 21 billion — the largest equity round ever completed by a European technology company.
| Role | Investor | Origin |
|---|---|---|
| Series D lead | Samsung Electronics | South Korea |
| Co-leads | Scaleup Europe Fund (EQT), PSG Equity | Sweden, United States |
| Series C lead | ASML (about 11 percent) | Netherlands |
| New entrants | Advent, BlackRock, Grand Duchy of Luxembourg | United States, Luxembourg |
| Existing backers | a16z, General Catalyst, Lightspeed, Salesforce Ventures | United States |
| Chip supplier and shareholder | Nvidia | United States |
The most notable fact in that table is the last row. Nvidia supplies the 3,800 chips the model was trained on, and sits among the investors in the round. The sole supplier of the critical component is also a shareholder in the customer.
To be fair: this arrangement is in no way specific to Mistral, Nvidia holding stakes across a great many companies in the sector. And a company can perfectly well be financed mostly by foreign capital while operating under European law — that is in fact true of most of the continent’s technology champions.
But when an announcement is headlined “Forged in Europe. Built for AI sovereignty”, readers are entitled to know that the lead investor in the latest round is South Korean, that the largest shareholder is Dutch, and that the chip supplier is also on the cap table.
One further element points the same way: Mistral has struck a strategic partnership with Microsoft, under which Microsoft uses capacity from Mistral’s European data centres to serve its own customers, and integrates Mistral’s models into Microsoft Foundry and Copilot Studio. The relationship runs both ways.
”In Europe”, not “in France”
A point of wording that was lost consistently in the coverage. Mistral writes “in Mistral’s own datacenters in Europe”. In Europe. Not in France.
The distinction comes from the company, not from us, and it matches its industrial reality. Mistral’s first data centre is indeed French: Bruyeres-le-Chatel, in Essonne, 44 MW, fitted with 13,800 Nvidia GB300 GPUs funded by 830 million dollars of debt raised in early 2026. But a second site, costing 1.2 billion euros, is under development in Sweden, and the company is targeting 200 MW of combined European capacity by the end of 2027.
The announcement does not say which of those sites was used to train Large 4. Stating that the model was “trained in France” therefore goes beyond what Mistral has published. It is likely, given the timetable of the two sites. It is not established.
The displayed price is a struck-through price
The official model card stacks two prices. The full price is struck through, the launch price is the one highlighted.
| Per million tokens | Full price | Launch price |
|---|---|---|
| Input | $1.36 | $0.68 |
| Cached input | $0.14 | $0.07 |
| Output | $4.18 | $2.09 |
No end date is published for this promotion. A company budgeting at $0.68 therefore needs to plan for a doubling without notice.
The second point is more structural. Mistral’s pricing page still lists “Mistral Large” at $0.5 input and $1.5 output, the rates of the previous generation. The full price of Large 4 therefore amounts to roughly 2.7 times the input price and 2.8 times the output price of Mistral Large 3.
That runs against the general movement of the sector, where prices at equal performance fall quarter after quarter. There is an explanation: the model is far bigger. But it deserves saying, because the coverage presented these rates as a competitiveness argument when, measured against Mistral’s own previous generation, they are an increase.
What our ranking measures, as of 8 October 2026
The Le Recul AI ranking aggregates measurements from several independent families of sources. In the 8 October 2026 collection, across 9,380 measurements, “Mistral large 4 preview” already appears.
These positions have to be read with the caution they demand. The model’s evaluation is still marked partial: it rests on a single family of sources and on a coverage of 44 on the generalist index. A model released three days earlier has not yet been measured by everyone, and its position will move.
- Generalist: 352nd out of 1,050 entries, score 59.13, partial evaluation.
- Cost-performance: 302nd out of 1,042 entries, score 71.97, full coverage.
One point, by contrast, depends on no measurement at all and will not move before the end of the month: Mistral Large 4 does not appear in our “open source” category. The four Mistral models that do are Small and 7B models. That is the mechanical consequence of the finding at the top of this article: what is downloadable from Mistral is not Large 4.
What cannot be verified: the “three times fewer chips”
One comparison has circulated widely since the announcement: that Mistral trained its model with three times fewer chips than the latest Chinese models. We tried to verify it. It cannot be.
Mistral publishes its figure: 3,800 Grace Blackwell GPUs. But none of the major Chinese labs of the current generation — DeepSeek V4, Qwen 3.8, Kimi K3 — publishes the size of its training cluster. The only figures available for those models concern inference requirements, which is an entirely different measurement.
The only Chinese training cluster published to date appears in the DeepSeek-V3 technical report: 2,048 H800 GPUs. That is fewer chips than Mistral used, from an earlier generation.
Comparing a published figure against figures that are not published does not produce a factor of three. This does not mean Mistral was not efficient — that is in fact plausible. It means nobody can establish it publicly today.
What the announcement establishes, and what it does not
Established, and solid. A model of a trillion parameters, 52 billion active, a one-million-token context window, trained from scratch on 3,800 chips in Europe by a European company. Claimed front-rank results in cybersecurity, finance and law. A European deployment operated end to end under European law. Training data covering more than 160 languages, including every official language of the Union. It is a real industrial achievement, and the only one of this scale in Europe.
Announced, but not yet delivered. The weights. The licence. The ability to install the model on your own premises. All three are promised for the end of October 2026, and all three are, on 9 October, empty boxes in the company’s own documentation.
Not established. That the model was trained in France rather than elsewhere in Europe. That it required three times fewer chips than the Chinese models. That its 82 percent record reflects technical superiority rather than a different moderation policy — the announcement itself says otherwise.
Open, in the literal sense. Which states get access to the reduced-moderation version, on what criteria, and for how long.
What to watch between now and the end of October
Three items, and only three, will decide what this announcement was worth.
The licence. If the weights ship under Apache 2.0, as Large 3 did, the promise is kept beyond what anyone could have demanded. If it is a bespoke licence with revenue conditions, as for Medium 3.5, “open” will mean something else. If it is a research licence, it will mean the opposite of what most readers understood.
The contents of the download. Published weights are not necessarily the weights served by the API. It will need checking whether the downloadable version matches the model that was tested, or a variant whose cyber capabilities — precisely the ones behind its record — have been reduced.
The price. The launch promotion has no published end date. Whether it is kept, or quietly expires, will tell us whether the reference price is $0.68 or $1.36.
We will update this article at each of those three milestones. In the meantime, the phrase that best sums up the state of play is Mistral’s own, in its own documentation: coming soon.
Further reading: in August 2026 we documented Mistral’s strategy of hosting a Chinese model on its own servers, and in June 2026 what “sovereign” means exactly when Mistral equips a bank. On the substance, we explained why China gives its models away for free and examined the distillation accusation aimed at Kimi K3. Finally, the AI Act has imposed transparency obligations since 2 August 2026 that bear directly on open-weight models. The standing of all these models is tracked in our AI ranking.